
最新的Databricks Certified Machine Learning Associate - Databricks-Machine-Learning-Associate免費考試真題
A data scientist has created two linear regression models. The first model uses price as a label variable and the second model uses log(price) as a label variable. When evaluating the RMSE of each model by comparing the label predictions to the actual price values, the data scientist notices that the RMSE for the second model is much larger than the RMSE of the first model.
Which of the following possible explanations for this difference is invalid?
Which of the following possible explanations for this difference is invalid?
正確答案: D
說明:(僅 Fast2test 成員可見)
A machine learning engineer has created a Feature Table new_table using Feature Store Client fs. When creating the table, they specified a metadata description with key information about the Feature Table. They now want to retrieve that metadata programmatically.
Which of the following lines of code will return the metadata description?
Which of the following lines of code will return the metadata description?
正確答案: D
說明:(僅 Fast2test 成員可見)
A data scientist is using Spark ML to engineer features for an exploratory machine learning project.
They decide they want to standardize their features using the following code block:
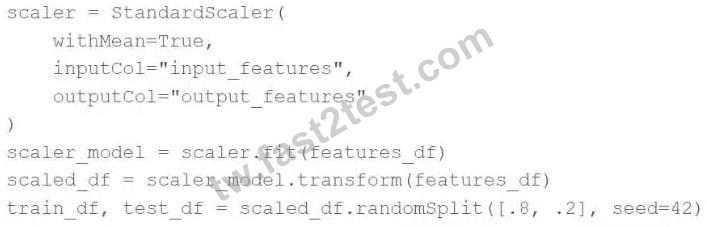
Upon code review, a colleague expressed concern with the features being standardized prior to splitting the data into a training set and a test set.
Which of the following changes can the data scientist make to address the concern?
They decide they want to standardize their features using the following code block:
Upon code review, a colleague expressed concern with the features being standardized prior to splitting the data into a training set and a test set.
Which of the following changes can the data scientist make to address the concern?
正確答案: B
說明:(僅 Fast2test 成員可見)
A machine learning engineer is trying to scale a machine learning pipeline by distributing its single-node model tuning process. After broadcasting the entire training data onto each core, each core in the cluster can train one model at a time. Because the tuning process is still running slowly, the engineer wants to increase the level of parallelism from 4 cores to 8 cores to speed up the tuning process. Unfortunately, the total memory in the cluster cannot be increased.
In which of the following scenarios will increasing the level of parallelism from 4 to 8 speed up the tuning process?
In which of the following scenarios will increasing the level of parallelism from 4 to 8 speed up the tuning process?
正確答案: E
說明:(僅 Fast2test 成員可見)
A data scientist is utilizing MLflow Autologging to automatically track their machine learning experiments. After completing a series of runs for the experiment experiment_id, the data scientist wants to identify the run_id of the run with the best root-mean-square error (RMSE).
Which of the following lines of code can be used to identify the run_id of the run with the best RMSE in experiment_id?
Which of the following lines of code can be used to identify the run_id of the run with the best RMSE in experiment_id?
正確答案: D
說明:(僅 Fast2test 成員可見)
A data scientist uses 3-fold cross-validation when optimizing model hyperparameters for a regression problem. The following root-mean-squared-error values are calculated on each of the validation folds:
* 10.0
* 12.0
* 17.0
Which of the following values represents the overall cross-validation root-mean-squared error?
* 10.0
* 12.0
* 17.0
Which of the following values represents the overall cross-validation root-mean-squared error?
正確答案: E
說明:(僅 Fast2test 成員可見)
A data scientist has developed a linear regression model using Spark ML and computed the predictions in a Spark DataFrame preds_df with the following schema:
prediction DOUBLE
actual DOUBLE
Which of the following code blocks can be used to compute the root mean-squared-error of the model according to the data in preds_df and assign it to the rmse variable?
prediction DOUBLE
actual DOUBLE
Which of the following code blocks can be used to compute the root mean-squared-error of the model according to the data in preds_df and assign it to the rmse variable?
正確答案: D
說明:(僅 Fast2test 成員可見)
A data scientist has been given an incomplete notebook from the data engineering team. The notebook uses a Spark DataFrame spark_df on which the data scientist needs to perform further feature engineering. Unfortunately, the data scientist has not yet learned the PySpark DataFrame API.
Which of the following blocks of code can the data scientist run to be able to use the pandas API on Spark?
Which of the following blocks of code can the data scientist run to be able to use the pandas API on Spark?
正確答案: D
說明:(僅 Fast2test 成員可見)